Live API 中的思考功能
Gemini Live API 讓你能與 Gemini 模型進行即時、雙向的語音對話。
標準語音模型很適合即時來回的對話:你對模型說話,模型便立即以語音回覆。但當某個要求需要規劃、複雜分析或外部工具時,直接回應便會碰到極限——模型只能在未經推理的情況下作答,或在等待工具完成時沉默停頓。
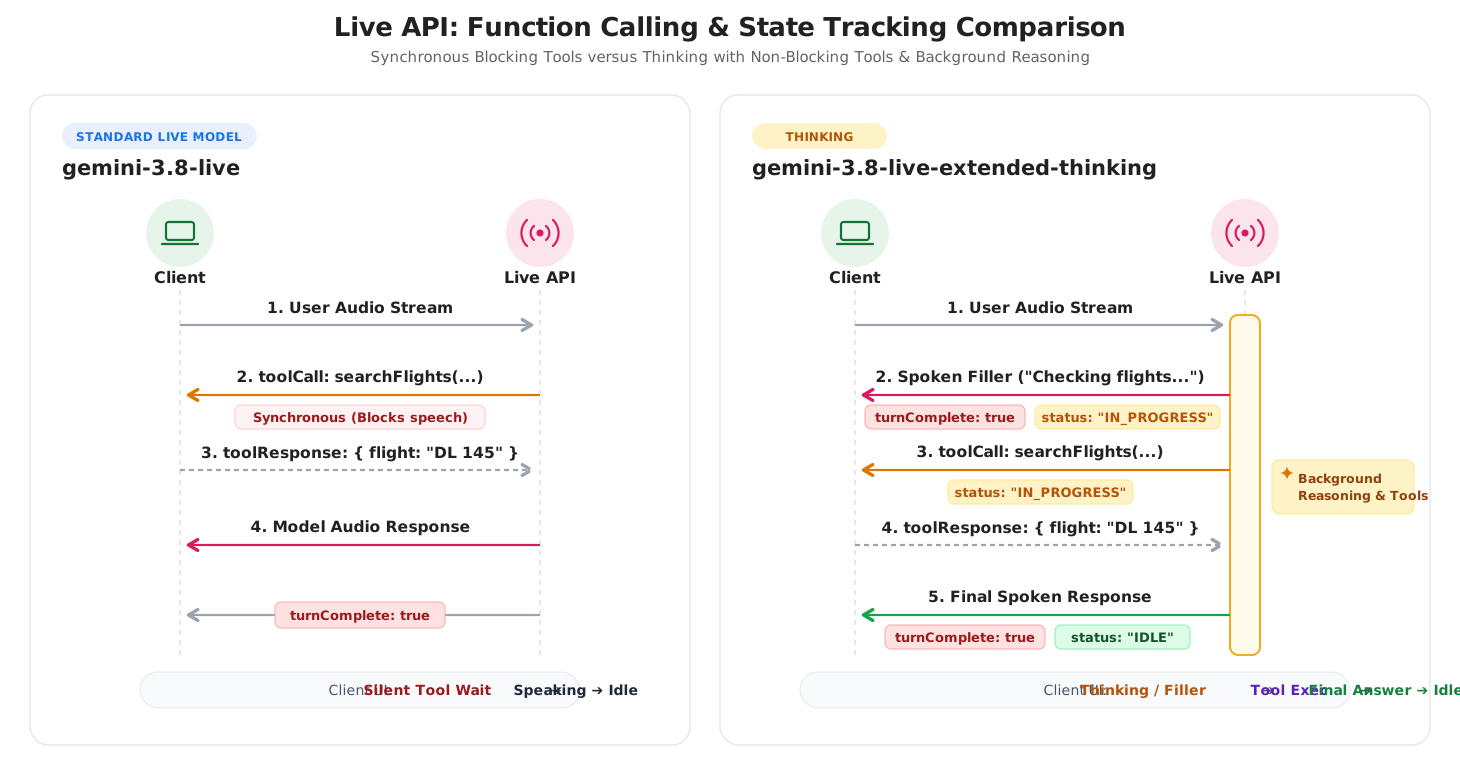
Live API 中的思考功能(gemini-3.8-live-extended-thinking)為即時語音工作階段加入了背景推理。模型會在背景規劃並呼叫非同步工具,同時說出自然的對話填充語,讓互動持續進行。
這樣的架構以兩種關鍵方式改變了對話生命週期:
- 對話填充語:模型在背景執行工具的同時,會說出中途更新(例如「正在查詢航班選項」)。
- 互動狀態追蹤:由於模型在單一要求中可能多次發言,伺服器會在背景處理期間發出
interaction_status: "IN_PROGRESS",並在整體任務完成時發出interaction_status: "IDLE"。
下圖比較了標準 Live 語音工作階段與具備背景推理的思考功能,兩者在互動生命週期上的差異:
選擇合適的模型
在 gemini-3.8-live 與 gemini-3.8-live-extended-thinking 之間做選擇時,請衡量三個主要因素:回應延遲、任務複雜度,以及用戶端狀態處理。
何時使用 Gemini 3.8 Live
若是低延遲的對話型語音代理,且即時輪替發言至關重要、任務又直接明確,請使用 gemini-3.8-live。
- 對話型語音助理:客戶服務分流、語言練習、語音搜尋與互動式說故事。
- 快速的工具執行:外部工具能在毫秒內回傳的工作流程(例如讀取感測器數值或控制智慧裝置)。
- 簡單的用戶端邏輯:每個使用者回合只收到一次模型回應,且
turnComplete: true能可靠表示工作階段已閒置的應用程式。
何時使用 Gemini 3.8 Live Extended Thinking
當你的代理必須評估複雜資料、規劃多個步驟,或處理需要數秒才能執行的工具時,請使用 gemini-3.8-live-extended-thinking。
- 多步驟診斷與支援:技術支援代理跨多份記錄、錯誤代碼與設定檢查,診斷系統問題。
- 協調式資料檢索:旅遊與訂票代理透過平行 API 呼叫搜尋航班、查詢飯店並比較價格。
- STEM 與程式教學:教育代理在說出解說前,先驗證公式、除錯程式碼或逐步推演多步驟邏輯。
- 遮掩工具延遲:若長時間執行的函式會讓聆聽者陷入尷尬沉默的語音體驗。
主要差異摘要
下表彙整了兩個模型之間的技術差異:
| 功能 | Gemini 3.8 Live | Gemini 3.8 Live Extended Thinking |
|---|---|---|
| 主要使用案例 | 低延遲語音代理、直接指令、快速工具 | 多步驟問題解決、複雜規劃、多工具工作流程 |
| 模型端點 | gemini-3.8-live |
gemini-3.8-live-extended-thinking |
| 推理架構 | 交錯推理,延遲設定固定(不支援 thinking_level) |
可設定的背景推理(thinking_level:low、medium、high;不支援 MINIMAL) |
| 回合邊界 | turnComplete: true 結束回合並回到閒置狀態 |
turnComplete: true 結束一次發言;interaction_status 控制工作階段生命週期 |
| 對話填充語 | 模型會等工具執行完畢才發言 | 模型在處理期間串流中途對話填充語 |
| 工具執行 | 支援同步(BLOCKING)與非同步(NON_BLOCKING)工具 |
要求使用非同步(NON_BLOCKING)工具宣告 |
遷移與整合路徑
請依照下列步驟,升級現有的語音應用程式,或將思考功能整合進你的 Live API 工作階段。
從 Gemini 3.1 Flash Live 升級
對於使用 gemini-3.1-flash-live-preview 的現有語音應用程式,升級至 gemini-3.8-live 需要更新模型字串,並在設定組態中省略 thinking_level(或 thinking_config),因為 thinking_level 在 gemini-3.8-live 上不受支援:
{
  "setup": {
    "model": "models/gemini-3.8-live"
  }
}
回合生命週期與 turnComplete 訊號維持不變。
採用思考功能
若要採用 gemini-3.8-live-extended-thinking,請更新三個整合點:
- 追蹤
interaction_status而非turnComplete:在思考工作階段中,模型會在推理的同時發出中途對話填充語。請檢查傳入伺服器訊息上的interaction_status欄位來管理 UI 狀態;只有在interaction_status為IDLE時才回到閒置狀態。
status = getattr(message, "interaction_status", None)
if status == "IDLE":
    # Ready for user input
    set_ui_state("listening")
elif status == "IN_PROGRESS":
    # Reasoning or executing tools
    set_ui_state("thinking")
if (message.interactionStatus === 'IDLE') {
  // Ready for user input
  setUiState('listening');
} else if (message.interactionStatus === 'IN_PROGRESS') {
  // Reasoning or executing tools
  setUiState('thinking');
}
- 宣告非阻斷函式:在所有函式宣告上設定
"behavior": "NON_BLOCKING"。思考模型會在背景非同步執行工具,同時串流口頭更新;同步阻斷工具會回傳錯誤。
search_flights = types.FunctionDeclaration(
    name="search_flights",
    description="Searches for available flights.",
    behavior="NON_BLOCKING",
    parameters={
        "type": "OBJECT",
        "properties": {
            "destination": {"type": "STRING"},
        },
        "required": ["destination"],
    },
)
const searchFlights = {
  name: 'search_flights',
  description: 'Searches for available flights.',
  behavior: 'NON_BLOCKING',
  parameters: {
    type: 'OBJECT',
    properties: {
      destination: { type: 'STRING' },
    },
    required: ['destination'],
  },
};
- 設定推理深度:在工作階段設定中設定
thinking_config,以調整推理等級(low、medium或high;不支援MINIMAL)。
config = types.LiveConnectConfig(
    response_modalities=["AUDIO"],
    thinking_config=types.ThinkingConfig(
        thinking_level="low",
    ),
    tools=[types.Tool(function_declarations=[search_flights])],
)
const config = {
  responseModalities: [Modality.AUDIO],
  thinkingConfig: {
    thinkingLevel: 'low',
  },
  tools: [{ functionDeclarations: [searchFlights] }],
};
通訊協定並排比較
本節比較 Live API 工作階段各階段所交換的 WebSocket 訊息。
步驟 1:工作階段設定
兩個模型連線至相同的 WebSocket 端點:
wss://generativelanguage.googleapis.com/ws/google.ai.generativelanguage.v1alpha.GenerativeService.BidiGenerateContent?key=$API_KEY
- 相同:WebSocket URL 與 API 金鑰驗證。
- 模型字串:
gemini-3.8-live對比gemini-3.8-live-extended-thinking。 - 思考設定:思考功能新增了
thinkingConfig,用以調整推理深度。 - 工具行為:思考功能要求函式宣告上帶有
"behavior": "NON_BLOCKING"。
{
  "setup": {
    "model": "models/gemini-3.8-live",
    "generationConfig": {
      "responseModalities": ["AUDIO"],
      "speechConfig": {
        "voiceConfig": {
          "prebuiltVoiceConfig": {
            "voiceName": "Puck"
          }
        }
      }
    }
  }
}
{
  "setup": {
    "model": "models/gemini-3.8-live-extended-thinking",
    "generationConfig": {
      "responseModalities": ["AUDIO"],
      "speechConfig": {
        "voiceConfig": {
          "prebuiltVoiceConfig": {
            "voiceName": "Puck"
          }
        }
      },
      "thinkingConfig": {
        "thinkingLevel": "LOW"
      }
    },
    "tools": [{
      "functionDeclarations": [{
        "name": "searchFlights",
        "description": "Searches for flights between cities.",
        "behavior": "NON_BLOCKING",
        "parameters": {
          "type": "OBJECT",
          "properties": {
            "destination": { "type": "STRING" }
          },
          "required": ["destination"]
        }
      }]
    }]
  }
}
兩個模型在連線時都會收到相同的伺服器確認:
{
  "setupComplete": {}
}
步驟 2:使用者音訊輸入
兩個模型的音訊串流方式相同。即時 16kHz 原始 PCM 音訊區塊會使用 realtimeInput 串流:
{
  "realtimeInput": {
    "audio": {
      "data": "UklGRiQAAABXQVZF...",
      "mimeType": "audio/pcm;rate=16000"
    }
  }
}
步驟 3:模型回應與狀態生命週期
兩個模型都會在 serverContent.modelTurn 中串流 24kHz PCM 音訊區塊。不過,生命週期的管理方式有所不同:
Gemini 3.8 Live 回應流程
- 伺服器串流該回合的音訊區塊。
- 伺服器傳送
turnComplete: true,表示模型已說完,工作階段處於閒置狀態。
// 1. Audio stream chunks
{
  "serverContent": {
    "modelTurn": {
      "parts": [
        {
          "inlineData": {
            "mimeType": "audio/pcm;rate=24000",
            "data": "..."
          }
        }
      ]
    }
  }
}

// 2. Turn completion -> Signals client to switch UI to Idle/Listening
{
  "serverContent": {
    "turnComplete": true
  }
}
Gemini 3.8 Live Extended Thinking 回應流程
- 口頭填充語:模型發出中途語音(例如 「正在查詢飛往西雅圖的航班……」),並帶有
turnComplete: true與interactionStatus: "IN_PROGRESS"。 - 非同步工具呼叫:伺服器在
interactionStatus維持"IN_PROGRESS"的同時發出工具呼叫,表示伺服器正在積極處理這個多步驟回合,並等待工具回應。 - 工具回應:用戶端執行該函式並回傳輸出。
- 最終回應:伺服器送出完整答案,並帶有
turnComplete: true與interactionStatus: "IDLE"。
// 1. Spoken verbal filler while background reasoning proceeds
{
  "serverContent": {
    "modelTurn": {
      "parts": [
        {
          "inlineData": {
            "mimeType": "audio/pcm;rate=24000",
            "data": "..."
          }
        }
      ]
    },
    "turnComplete": true,
    "interactionStatus": "IN_PROGRESS"
  }
}

// 2. Asynchronous tool call emitted with IN_PROGRESS status
{
  "toolCall": {
    "functionCalls": [
      {
        "id": "call_123",
        "name": "searchFlights",
        "args": {
          "destination": "Seattle"
        }
      }
    ]
  },
  "interactionStatus": "IN_PROGRESS"
}

// 3. Client executes function and returns result
{
  "toolResponse": {
    "functionResponses": [
      {
        "response": {
          "output": {
            "flight": "DL 145",
            "price": "$145"
          }
        },
        "id": "call_123"
      }
    ]
  }
}

// 4. Final spoken answer delivered -> session transitions to IDLE when done
{
  "serverContent": {
    "modelTurn": {
      "parts": [
        {
          "inlineData": {
            "mimeType": "audio/pcm;rate=24000",
            "data": "..."
          }
        }
      ]
    },
    "interactionStatus": "IDLE",
    "turnComplete": true
  }
}
SDK 實作範例
下列範例示範如何使用 Google GenAI SDK 設定思考功能,並處理 interaction_status。
import asyncio
from google import genai
from google.genai import types

client = genai.Client(http_options={"api_version": "v1beta"})
model = "gemini-3.8-live-extended-thinking"

# Define non-blocking function declaration
search_flights = types.FunctionDeclaration(
    name="search_flights",
    description="Searches for available flights to a destination.",
    behavior="NON_BLOCKING",
    parameters={
        "type": "OBJECT",
        "properties": {
            "destination": {"type": "STRING"}
        },
        "required": ["destination"]
    }
)

config = types.LiveConnectConfig(
    response_modalities=["AUDIO"],
    thinking_config=types.ThinkingConfig(
        thinking_level="low"
    ),
    tools=[types.Tool(function_declarations=[search_flights])]
)

async def main():
    async with client.aio.live.connect(model=model, config=config) as session:
        print("Session connected with Thinking")

        async for message in session.receive():
            # Inspect interaction status for server lifecycle tracking
            status = getattr(message, "interaction_status", None)
            if status:
                print(f"Interaction status: {status}")

            # Handle audio output parts
            if message.server_content and message.server_content.model_turn:
                for part in message.server_content.model_turn.parts:
                    if part.inline_data:
                        # Process 24kHz audio chunk
                        pass

            # Handle asynchronous tool call
            if message.tool_call:
                for call in message.tool_call.function_calls:
                    print(f"Executing tool: {call.name}")
                    # Simulate function execution
                    response = types.FunctionResponse(
                        id=call.id,
                        name=call.name,
                        response={"result": "Flight DL 145 ($145)"}
                    )
                    await session.send_tool_response(
                        function_responses=[response]
                    )

            # Status is IDLE when reasoning and all turns are complete
            if status == "IDLE":
                print("Session is idle and ready for user input.")

if __name__ == "__main__":
    asyncio.run(main())
import { GoogleGenAI, Modality } from '@google/genai';

const ai = new GoogleGenAI({ httpOptions: { apiVersion: "v1beta" } });
const model = 'gemini-3.8-live-extended-thinking';

const searchFlights = {
  name: 'search_flights',
  description: 'Searches for available flights to a destination.',
  behavior: 'NON_BLOCKING',
  parameters: {
    type: 'OBJECT',
    properties: {
      destination: { type: 'STRING' }
    },
    required: ['destination']
  }
};

const config = {
  responseModalities: [Modality.AUDIO],
  thinkingConfig: {
    thinkingLevel: 'low'
  },
  tools: [{ functionDeclarations: [searchFlights] }]
};

async function main() {
  const session = await ai.live.connect({
    model: model,
    config: config,
    callbacks: {
      onopen: () => console.log('Session connected'),
      onmessage: async (event) => {
        const message = JSON.parse(event.data);

        if (message.interactionStatus) {
          console.log(`Interaction status: ${message.interactionStatus}`);
        }

        if (message.toolCall) {
          for (const call of message.toolCall.functionCalls) {
            console.log(`Executing tool: ${call.name}`);
            session.sendToolResponse({
              functionResponses: [{
                id: call.id,
                name: call.name,
                response: { result: 'Flight DL 145 ($145)' }
              }]
            });
          }
        }

        if (message.interactionStatus === 'IDLE') {
          console.log('Session is idle and waiting for input.');
        }
      }
    }
  });
}

main();
後續步驟
- 閱讀 Gemini 3.8 Live 與 Gemini 3.8 Live Extended Thinking 模型頁面。
- 查看模型比較表,了解所有 Live API 模型的詳細功能比較。
- 在 Live API 工具使用指南中進一步了解函式呼叫。
- 檢閱工作階段管理,了解如何處理工作階段恢復與上下文生命週期。