語音複製
語音複製可讓你透過 Gemini API 的 Voices 端點(POST /v1beta/voices),從一段
簡短的音訊範本複製說話者的聲音特徵。
Gemini 3.8 Flash TTS
(gemini-3.8-flash-tts)與
Gemini 3.8 Flash-Lite TTS
(gemini-3.8-flash-lite-tts)皆支援語音複製。
複製語音、驗證同意並試聽複製後語音的最快方式,是使用
Google AI Studio 中互動式的 Voice Replication 體驗。你可以直接在瀏覽器中錄製
或上傳參考片段與同意片段,預覽
語音,並將產生的 voice_... ID 直接複製到你的應用程式
程式碼中。
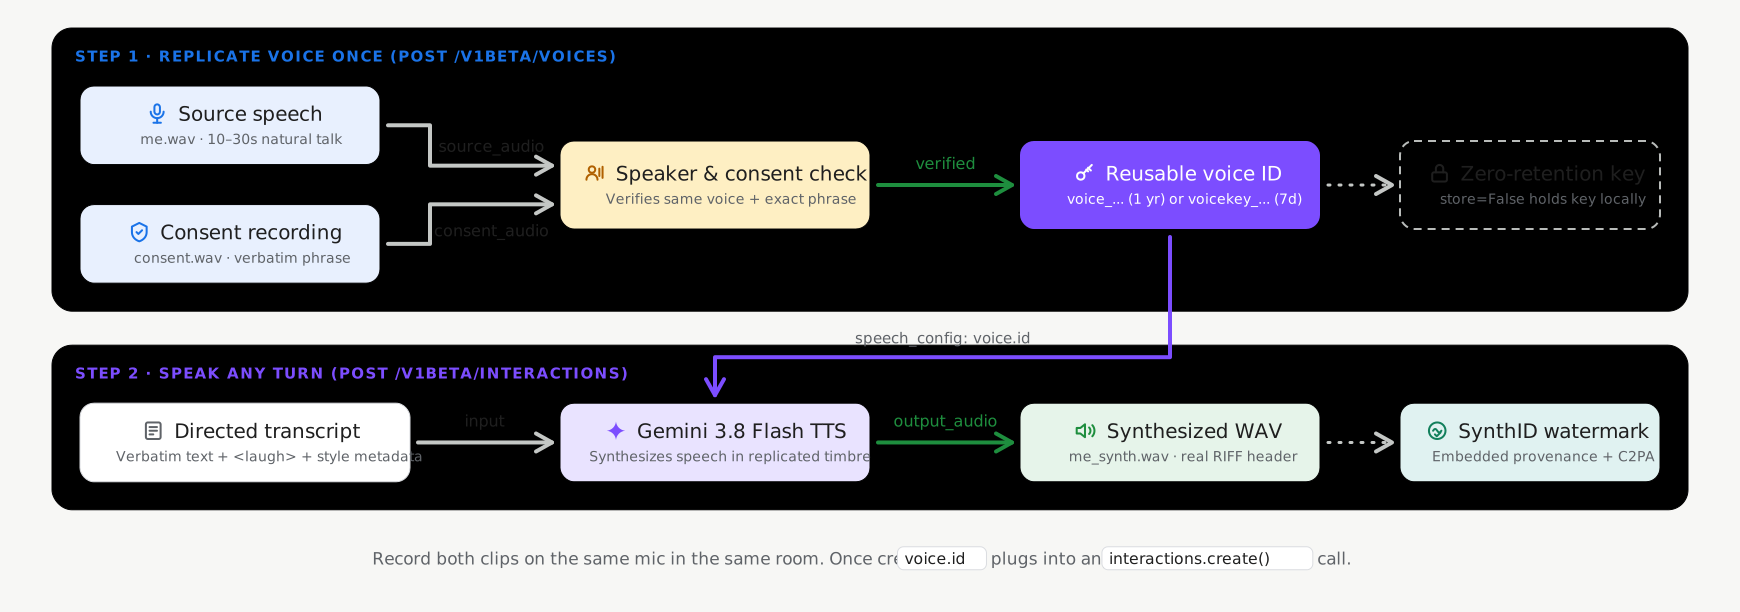
有狀態與無狀態儲存模式
呼叫 voices.create
(POST /v1beta/voices)時,語音複製支援兩種儲存模式,預設啟用有狀態儲存:
- 有狀態儲存(
store=True,建議的預設值):Google 會將你 已驗證的語音設定檔儲存在你的專案中,並回傳輕量且持久的voice_id(replicated_voice.id,例如voice_abc123...)。你可以在 不同請求之間傳遞這個voice_id,並透過voices.list()、voices.get()與voices.delete()加以管理。 - 無狀態、由用戶端管理的金鑰(
store=False,選用):若工作負載 要求生物特徵語音設定檔在伺服器端零持久化,請設定store=False。API 會回傳加密且自成一體的voice_key(replicated_voice.key,以voicekey_...開頭),由你的應用程式 儲存在本機,並在合成請求中直接傳遞。
| 儲存模式 | 識別碼 | 專案上限 | 保留期限(TTL) |
|---|---|---|---|
有狀態語音(store=True) |
voice_... |
每個專案 200 個語音(提示詞建立與複製的語音共用) | 自最後一次使用起 1 年(滑動式 expire_time;合成時重設) |
無狀態語音金鑰(store=False) |
voicekey_... |
由用戶端管理 | 自建立起 7 天(固定 expire_time;使用 voices.create 續期) |
- 配額層級與區域可用性:語音複製需要 付費層級(Tier 1 或更高)的 Gemini API 專案(請參閱 速率限制);無需另外加入許可清單。此功能 在所有 Gemini API 支援的區域 皆可使用, 包括歐洲經濟區(EEA/EU)、英國與 瑞士。
- 資料儲存與刪除(
store=True):有狀態儲存會將 擷取出的聲音條件特徵持久保存在你的專案中,而非完整的 原始consent_audio錄音。呼叫voices.delete()會立即移除 專案中已儲存的語音設定檔及其條件資料。 - 浮水印與來源追溯:所有合成音訊都包含難以察覺的
SynthID 音訊浮水印。
輸入的
source_audio與consent_audio必須是真人真實錄音; 合成語音,或含有既有 SynthID 或 C2PA 浮水印的音訊, 會在驗證時遭到拒絕。
音訊與同意要求
每個 CreateVoice 複製請求都需要兩段真人音訊錄音,
且必須來自同一位成年說話者(建議使用 24kHz 單聲道 16 位元 WAV):
- 參考音訊(
source_audio):一段 10–30 秒的片段,內容為 你想複製其語音的說話者清晰、自然的說話聲。 - 同意音訊(
consent_audio):同一位說話者以其中一種 支援的語言 清楚朗讀強制同意聲明的錄音 (例如英文版):> 「I am the owner of this voice and I consent to Google using this voice to > create a synthetic voice model.」
建立複製語音(有狀態預設模式)
使用 Google GenAI SDK(google-genai 2.25.0+ / @google/genai 2.24.0+)或 REST API,
並設定 store=True,即可在你的專案中建立並儲存複製語音設定檔:
import base64
from google import genai

client = genai.Client(http_options={"api_version": "v1beta"})

with open("reference_speaker.wav", "rb") as f:
    source_b64 = base64.b64encode(f.read()).decode("utf-8")

with open("speaker_consent.wav", "rb") as f:
    consent_b64 = base64.b64encode(f.read()).decode("utf-8")

# Create a persistent replicated voice (store=True)
replicated_voice = client.voices.create(
    store=True,
    voice={
        "model": "gemini-3.8-flash-tts",
        "type": "replicated",
        "display_name": "Custom Replicated Speaker",
        "replicated": {
            "source_audio": {
                "mime_type": "audio/wav",
                "data": source_b64,
            },
            "consent_audio": {
                "mime_type": "audio/wav",
                "data": consent_b64,
            },
        },
    },
)

print(f"Created voice ID: {replicated_voice.id}")
import * as fs from "node:fs";
import { GoogleGenAI } from "@google/genai";

const ai = new GoogleGenAI({ httpOptions: { apiVersion: "v1beta" } });

const sourceB64 = fs.readFileSync("reference_speaker.wav").toString("base64");
const consentB64 = fs.readFileSync("speaker_consent.wav").toString("base64");

// Create a persistent replicated voice (store: true)
const replicatedVoice = await ai.voices.create({
  store: true,
  voice: {
    model: "gemini-3.8-flash-tts",
    type: "replicated",
    display_name: "Custom Replicated Speaker",
    replicated: {
      source_audio: {
        mime_type: "audio/wav",
        data: sourceB64,
      },
      consent_audio: {
        mime_type: "audio/wav",
        data: consentB64,
      },
    },
  },
});

console.log(`Created voice ID: ${replicatedVoice.id}`);
SOURCE_B64=$(base64 -w 0 reference_speaker.wav)
CONSENT_B64=$(base64 -w 0 speaker_consent.wav)

curl "https://generativelanguage.googleapis.com/v1beta/voices" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -X POST \
  -d "{
    \"store\": true,
    \"voice\": {
      \"model\": \"gemini-3.8-flash-tts\",
      \"type\": \"replicated\",
      \"display_name\": \"Custom Replicated Speaker\",
      \"replicated\": {
        \"source_audio\": {
          \"mime_type\": \"audio/wav\",
          \"data\": \"$SOURCE_B64\"
        },
        \"consent_audio\": {
          \"mime_type\": \"audio/wav\",
          \"data\": \"$CONSENT_B64\"
        }
      }
    }
  }"
使用複製語音合成語音
在合成請求中傳入回傳的 id(voice_...):
import base64
from google import genai

client = genai.Client(http_options={"api_version": "v1beta"})

interaction = client.interactions.create(
    model="gemini-3.8-flash-tts",
    input=[{
        "type": "user_input",
        "content": [{
            "type": "text",
            "text": (
                "Hello! This audio was synthesized using a replicated"
                " speaker voice."
            ),
            "annotations": [{
                "type": "speech_metadata",
                "style": "warm and conversational",
            }],
        }],
    }],
    response_format={"type": "audio"},
    generation_config={
        "speech_config": [
            {"voice": replicated_voice.id},
        ]
    },
)

with open("replicated_speech.wav", "wb") as f:
    f.write(base64.b64decode(interaction.output_audio.data))
import * as fs from "node:fs";
import { GoogleGenAI } from "@google/genai";

const ai = new GoogleGenAI({ httpOptions: { apiVersion: "v1beta" } });

const interaction = await ai.interactions.create({
  model: "gemini-3.8-flash-tts",
  input: [{
    type: "user_input",
    content: [{
      type: "text",
      text: "Hello! This audio was synthesized using a replicated speaker voice.",
      annotations: [{
        type: "speech_metadata",
        style: "warm and conversational",
      }],
    }],
  }],
  response_format: { type: "audio" },
  generation_config: {
    speech_config: [
      { voice: replicatedVoice.id },
    ],
  },
});

if (interaction.output_audio?.data) {
  fs.writeFileSync("replicated_speech.wav", Buffer.from(interaction.output_audio.data, "base64"));
}
curl "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -X POST \
  -d '{
    "model": "gemini-3.8-flash-tts",
    "input": [{
      "type": "user_input",
      "content": [{
        "type": "text",
        "text": "Hello! This audio was synthesized using a replicated speaker voice.",
        "annotations": [{
          "type": "speech_metadata",
          "style": "warm and conversational"
        }]
      }]
    }],
    "response_format": {"type": "audio"},
    "generation_config": {
      "speech_config": [
        {"voice": "voice_YOUR_REPLICATED_VOICE_ID"}
      ]
    }
  }' | jq -r '[.steps[] | select(.type=="model_output") | .content[] | select(.type=="audio")] | last | .data' | base64 --decode > out.wav
管理已儲存的複製語音
以 store=True 建立的複製語音,可透過 Voices API 列出、篩選、
檢視與刪除(所有篩選參數請參閱
擴充語音庫與篩選):
from google import genai

client = genai.Client(http_options={"api_version": "v1beta"})

# List stored replicated voices in your project
response = client.voices.list(type_=["replicated"])
for voice in response.voices or []:
    print(voice.id, voice.display_name, voice.type)

# Retrieve a specific voice by ID
voice_details = client.voices.get(id=replicated_voice.id)

# Delete a stored replicated voice
client.voices.delete(id=replicated_voice.id)
import { GoogleGenAI } from "@google/genai";

const ai = new GoogleGenAI({ httpOptions: { apiVersion: "v1beta" } });

// List stored replicated voices in your project
const response = await ai.voices.list({ type: ["replicated"] });
for (const voice of response.voices ?? []) {
  console.log(voice.id, voice.display_name, voice.type);
}

// Retrieve a specific voice by ID
const voiceDetails = await ai.voices.get(replicatedVoice.id);

// Delete a stored replicated voice
await ai.voices.delete(replicatedVoice.id);
# List stored replicated voices in your project
curl -G "https://generativelanguage.googleapis.com/v1beta/voices" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  --data-urlencode "type=replicated"

# Retrieve a specific voice by ID
curl "https://generativelanguage.googleapis.com/v1beta/voices/voice_YOUR_REPLICATED_VOICE_ID" \
  -H "x-goog-api-key: $GEMINI_API_KEY"

# Delete a stored replicated voice
curl -X DELETE "https://generativelanguage.googleapis.com/v1beta/voices/voice_YOUR_REPLICATED_VOICE_ID" \
  -H "x-goog-api-key: $GEMINI_API_KEY"
選項:無狀態、由用戶端管理的語音金鑰(store=False)
若你的應用程式要求語音設定檔在伺服器端零持久化,請在建立複製語音時設定
store=False。API 會回傳與你的專案綁定的加密
voice_key(replicated_voice.key,以 voicekey_... 開頭)及其 expire_time,由你儲存在用戶端,
並可在任何接受 voice ID 的位置直接傳入。
- 金鑰 7 天到期與續期:無狀態的
voicekey_...權杖 自建立起有固定的 7 天有效期限(replicated_voice.expire_time); 在合成中使用已過期的金鑰會回傳400 INVALID_ARGUMENT。若要在 無狀態金鑰到期前或到期後續期,請再次呼叫voices.create(POST /v1beta/voices)並設定store=False,使用先前儲存的同一份source_audio與consent_audio錄音——說話者無需 重新錄音。服務會重新驗證錄音,並回傳新的voicekey_...,附帶全新的 7 天expire_time。
import base64
from google import genai

client = genai.Client(http_options={"api_version": "v1beta"})

with open("reference_speaker.wav", "rb") as f:
    source_b64 = base64.b64encode(f.read()).decode("utf-8")

with open("speaker_consent.wav", "rb") as f:
    consent_b64 = base64.b64encode(f.read()).decode("utf-8")

# Create a stateless client-managed voice key (store=False)
replicated_voice = client.voices.create(
    store=False,
    voice={
        "model": "gemini-3.8-flash-tts",
        "type": "replicated",
        "replicated": {
            "source_audio": {"mime_type": "audio/wav", "data": source_b64},
            "consent_audio": {"mime_type": "audio/wav", "data": consent_b64},
        },
    },
)

# Pass replicated_voice.key ("voicekey_...") directly as the speaker voice
interaction = client.interactions.create(
    model="gemini-3.8-flash-tts",
    input=[{
        "type": "user_input",
        "content": [{
            "type": "text",
            "text": "Hello! This audio uses a stateless client-managed voice key.",
            "annotations": [{
                "type": "speech_metadata",
                "style": "warm and conversational",
            }],
        }],
    }],
    response_format={"type": "audio"},
    generation_config={
        "speech_config": [
            {"voice": replicated_voice.key},
        ]
    },
)
import * as fs from "node:fs";
import { GoogleGenAI } from "@google/genai";

const ai = new GoogleGenAI({ httpOptions: { apiVersion: "v1beta" } });

const sourceB64 = fs.readFileSync("reference_speaker.wav").toString("base64");
const consentB64 = fs.readFileSync("speaker_consent.wav").toString("base64");

// Create a stateless client-managed voice key (store: false)
const replicatedVoice = await ai.voices.create({
  store: false,
  voice: {
    model: "gemini-3.8-flash-tts",
    type: "replicated",
    replicated: {
      source_audio: { mime_type: "audio/wav", data: sourceB64 },
      consent_audio: { mime_type: "audio/wav", data: consentB64 },
    },
  },
});

// Pass replicatedVoice.key ("voicekey_...") directly as the speaker voice
const interaction = await ai.interactions.create({
  model: "gemini-3.8-flash-tts",
  input: [{
    type: "user_input",
    content: [{
      type: "text",
      text: "Hello! This audio uses a stateless client-managed voice key.",
      annotations: [{
        type: "speech_metadata",
        style: "warm and conversational",
      }],
    }],
  }],
  response_format: { type: "audio" },
  generation_config: {
    speech_config: [
      { voice: replicatedVoice.key },
    ],
  },
});
SOURCE_B64=$(base64 -w 0 reference_speaker.wav)
CONSENT_B64=$(base64 -w 0 speaker_consent.wav)

curl "https://generativelanguage.googleapis.com/v1beta/voices" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -X POST \
  -d "{
    \"store\": false,
    \"voice\": {
      \"model\": \"gemini-3.8-flash-tts\",
      \"type\": \"replicated\",
      \"replicated\": {
        \"source_audio\": {\"mime_type\": \"audio/wav\", \"data\": \"$SOURCE_B64\"},
        \"consent_audio\": {\"mime_type\": \"audio/wav\", \"data\": \"$CONSENT_B64\"}
      }
    }
  }"
各語言支援的同意語句
同意音訊必須以 30 種支援語言地區設定中的其中一種,清楚朗讀完全一致的聲明:
| 語言 | 地區設定(lang_id) |
逐字同意聲明 |
|---|---|---|
| 阿拉伯語 | ar-XA |
أنا مالك هذا الصوت وأوافق على أن تستخدم Google هذا الصوت لإنشاء نموذج صوتي اصطناعي. |
| 孟加拉語 | bn-IN |
আমি এই ভয়েসের মালিক এবং আমি একটি সিন্থেটিক ভয়েস মডেল তৈরি করতে এই ভয়েস ব্যবহার করে Google-এর সাথে সম্মতি দিচ্ছি। |
| 中文(簡體) | zh-CN |
我是此声音的拥有者并授权谷歌使用此声音创建语音合成模型 |
| 荷蘭語 | nl-NL |
Ik ben de eigenaar van deze stem en ik geef Google toestemming om deze stem te gebruiken om een synthetisch stemmodel te maken. |
| 英語(美國) | en-US |
I am the owner of this voice and I consent to Google using this voice to create a synthetic voice model. |
| 英語(英國) | en-GB |
I am the owner of this voice and I consent to Google using this voice to create a synthetic voice model. |
| 英語(印度) | en-IN |
I am the owner of this voice and I consent to Google using this voice to create a synthetic voice model. |
| 英語(澳洲) | en-AU |
I am the owner of this voice and I consent to Google using this voice to create a synthetic voice model. |
| 法語(法國) | fr-FR |
Je suis le propriétaire de cette voix et j'autorise Google à utiliser cette voix pour créer un modèle de voix synthétique. |
| 法語(加拿大) | fr-CA |
Je suis le propriétaire de cette voix et j'autorise Google à utiliser cette voix pour créer un modèle de voix synthétique. |
| 德語 | de-DE |
Ich bin der Eigentümer dieser Stimme und bin damit einverstanden, dass Google diese Stimme zur Erstellung eines synthetischen Stimmmodells verwendet. |
| 古吉拉特語 | gu-IN |
હું આ વોઈસનો માલિક છું અને સિન્થેટિક વોઈસ મોડલ બનાવવા માટે આ વોઈસનો ઉપયોગ કરીને google ને હું સંમતિ આપું છું |
| 印地語 | hi-IN |
मैं इस आवाज का मालिक हूं और मैं सिंथेटिक आवाज मॉडल बनाने के लिए Google को इस आवाज का उपयोग करने की सहमति देता हूं |
| 印尼語 | id-ID |
Saya pemilik suara ini dan saya menyetujui Google menggunakan suara ini untuk membuat model suara sintetis. |
| 義大利語 | it-IT |
Sono il proprietario di questa voce e acconsento che Google la utilizzi per creare un modello di voce sintetica. |
| 日語 | ja-JP |
私はこの音声の所有者であり、Googleがこの音声を使用して音声合成モデルを作成することを承認します。 |
| 卡納達語 | kn-IN |
ನಾನು ಈ ಧ್ವನಿಯ ಮಾಲಿಕ ಮತ್ತು ಸಂಶ್ಲೇಷಿತ ಧ್ವನಿ ಮಾದರಿಯನ್ನು ರಚಿಸಲು ಈ ಧ್ವನಿಯನ್ನು ಬಳಸಿಕೊಂಡುಗೂಗಲ್ ಗೆ ನಾನು ಸಮ್ಮತಿಸುತ್ತೇನೆ. |
| 韓語 | ko-KR |
나는 이 음성의 소유자이며 구글이 이 음성을 사용하여 음성 합성 모델을 생성할 것을 허용합니다. |
| 馬拉雅拉姆語 | ml-IN |
ഈ ശബ്ദത്തിന്റെ ഉടമ ഞാനാണ്, ഒരു സിന്തറ്റിക് വോയ്സ് മോഡൽ സൃഷ്ടിക്കാൻ ഈ ശബ്ദം ഉപയോഗിക്കുന്നതിന് ഞാൻ Google-ന് സമ്മതം നൽകുന്നു. |
| 馬拉地語 | mr-IN |
मी या आवाजाचा मालक आहे आणि सिंथेटिक व्हॉइस मॉडेल तयार करण्यासाठी हा आवाज वापरण्यासाठी मी Google ला संमती देतो |
| 波蘭語 | pl-PL |
Jestem właścicielem tego głosu i wyrażam zgodę na wykorzystanie go przez Google w celu utworzenia syntetycznego modelu głosu. |
| 葡萄牙語(巴西) | pt-BR |
Eu sou o proprietário desta voz e autorizo o Google a usá-la para criar um modelo de voz sintética. |
| 俄語 | ru-RU |
Я являюсь владельцем этого голоса и даю согласие Google на использование этого голоса для создания модели синтетического голоса. |
| 西班牙語(西班牙) | es-ES |
Soy el propietario de esta voz y doy mi consentimiento para que Google la utilice para crear un modelo de voz sintética. |
| 西班牙語(美國) | es-US |
Soy el propietario de esta voz y doy mi consentimiento para que Google la utilice para crear un modelo de voz sintética. |
| 坦米爾語 | ta-IN |
நான் இந்த குரலின் உரிமையாளர் மற்றும் செயற்கை குரல் மாதிரியை உருவாக்க இந்த குரலை பயன்படுத்த குகல்க்கு நான் ஒப்புக்கொள்கிறேன். |
| 泰盧固語 | te-IN |
నేను ఈ వాయిస్ యజమానిని మరియు సింతటిక్ వాయిస్ మోడల్ ని రూపొందించడానికి ఈ వాయిస్ ని ఉపయోగించడానికి googleకి నేను సమ్మతిస్తున్నాను. |
| 泰語 | th-TH |
ฉันเป็นเจ้าของเสียงนี้ และฉันยินยอมให้ Google ใช้เสียงนี้เพื่อสร้างแบบจำลองเสียงสังเคราะห์ |
| 土耳其語 | tr-TR |
Bu sesin sahibi benim ve Google'ın bu sesi kullanarak sentetik bir ses modeli oluşturmasına izin veriyorum. |
| 越南語 | vi-VN |
Tôi là chủ sở hữu giọng nói này và tôi đồng ý cho Google sử dụng giọng nói này để tạo mô hình giọng nói tổng hợp. |
錄製參考音訊的最佳做法
- 在安靜的環境中錄製:盡量減少室內回音、背景噪音、 音樂與重疊的人聲。
- 保持錄音條件一致:使用同一支麥克風、在相同的聲學環境中錄製
source_audio與consent_audio,讓說話者驗證能可靠通過。 - 轉換為 24kHz 單聲道 WAV:為獲得最佳效果,請在編碼前將輸入音訊重新取樣為 24kHz 單聲道 16 位元 PCM WAV。